 Datvero
What a Make com error notification really tells you
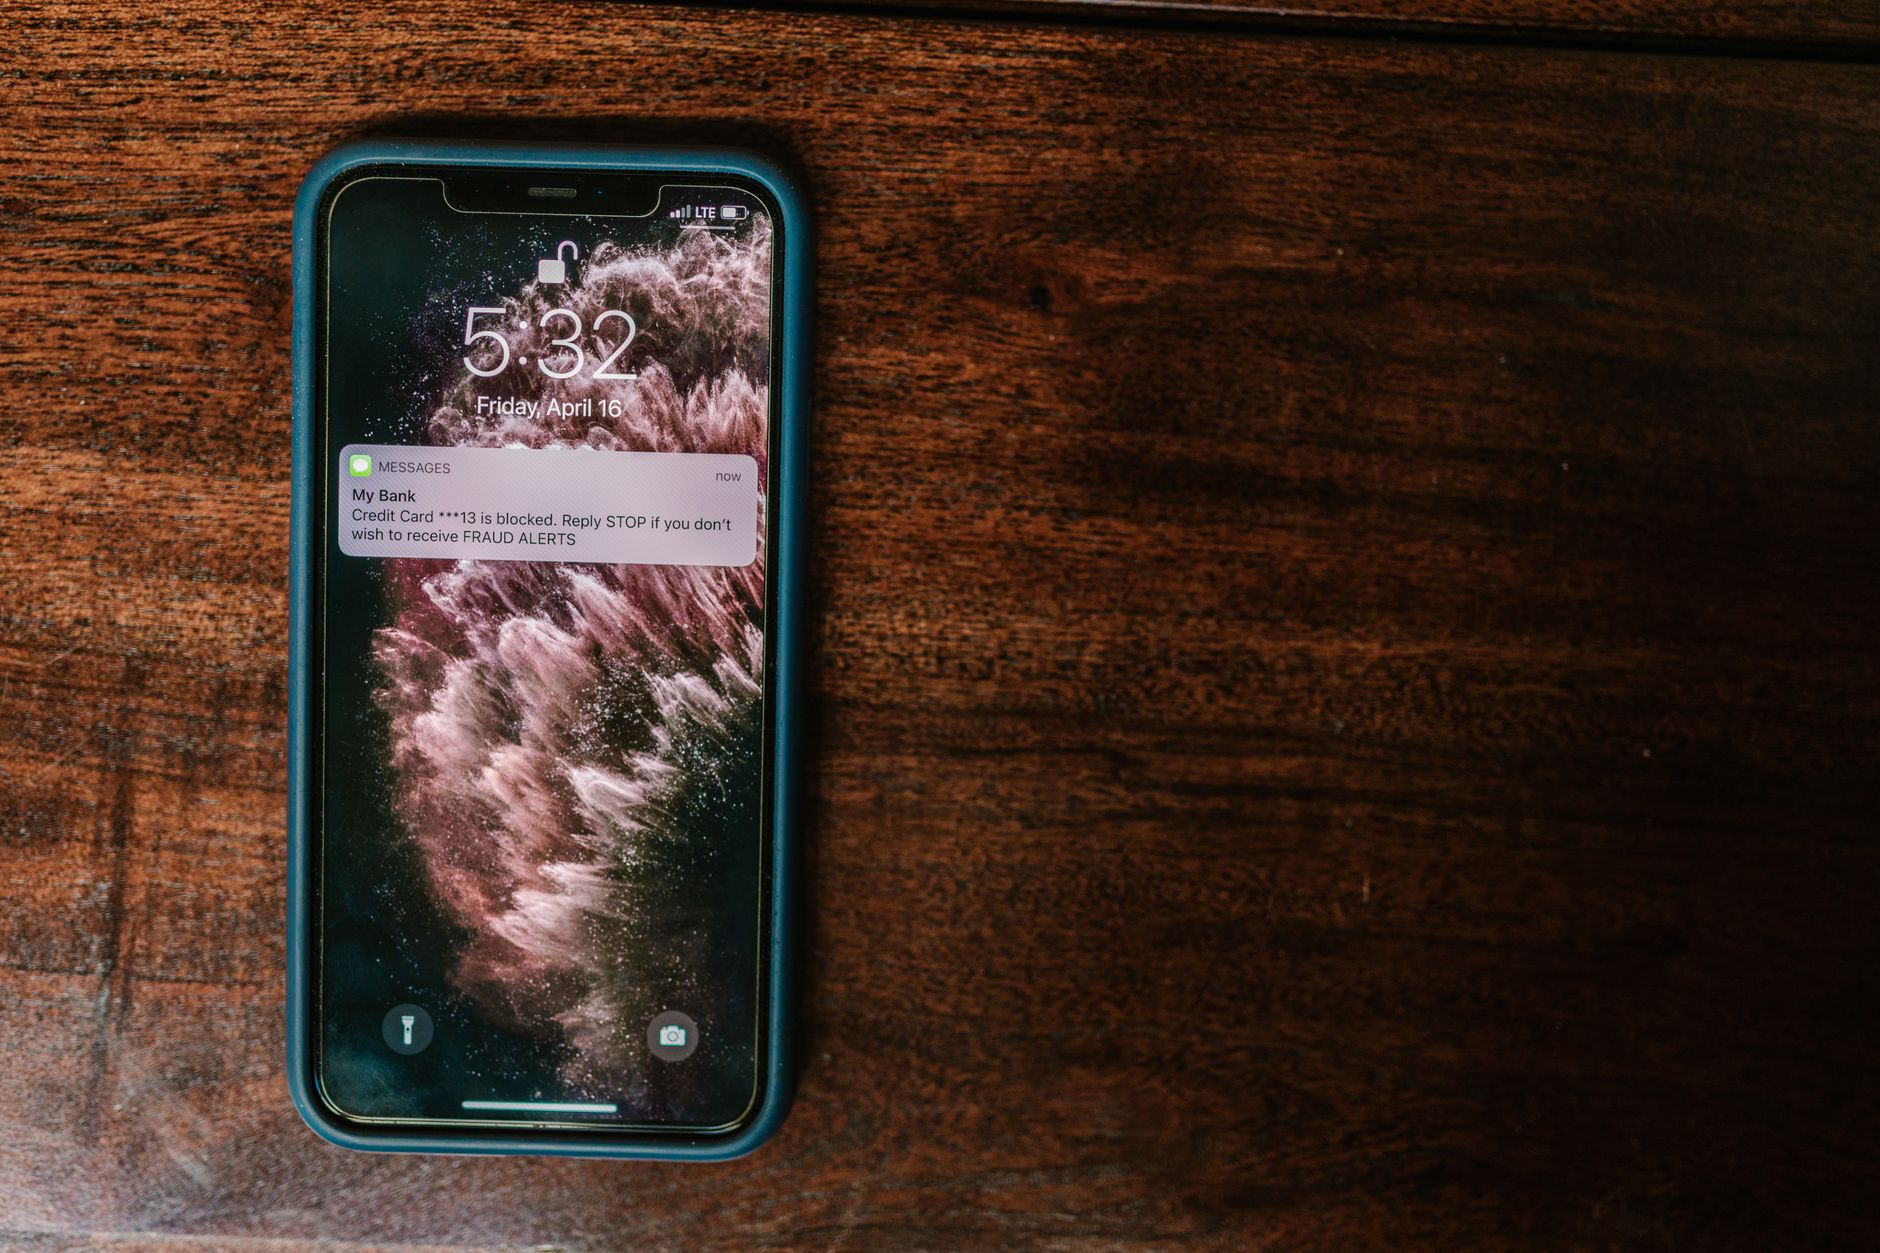
When a Make scenario fails, the first signal many teams see is a make com error notification. Check your own Make account and Make's current documentation for three details: what the message contains, where it is delivered and what is enabled by default. These can vary by setup and change over time, so do not build a process around an assumed format.
Whatever the format, read the alert as a pointer, not a diagnosis. It indicates that one execution went wrong. It rarely tells you whether the problem is isolated, whether downstream systems now hold partial data, or whether the next run will fail too.
That gap matters before you act. Rerunning a scenario can fix a transient timeout, or it can duplicate orders, resend customer messages or overwrite records.
Limits: failures an error notification will not catch
A notification generally depends on a run that ends in a recognised error. Several reliability problems never look like errors:
Each needs its own safeguard. Check expected run or item volume, validate data inside the scenario, review error-handling routes periodically, and send alerts to a destination owned by a team.
- A scenario switched off or paused, so nothing runs and nothing fails.
- A trigger that never fires, such as a webhook the upstream system stopped calling.
- A run that succeeds but processes empty, partial or malformed data.
- An error-handling route that absorbs failures and suppresses the signal.
- Alerts sent to one person who is away.
Turning an alert into actionable context
An alert is actionable when the recipient can choose the next step without reconstructing the situation. A common approach is an error-handling route that posts a structured message to a shared channel or ticketing tool. The message should contain:
Error payloads can contain names, email addresses or tokens. Pass identifiers rather than full records, and restrict the alert channel at least as tightly as the source systems. No alerting shortcut should grant wider visibility than the underlying access controls allow.
- Scenario name and a link to the failed run.
- The failing module and the error message as returned.
- A record identifier, such as an order number, not full personal data.
- Whether earlier modules already wrote to another system.
- The named owner or rota for the scenario.
Controlled recovery: deciding whether to retry
Recovery should be a decision, not a reflex. Some errors are transient, such as timeouts, rate limits or a brief outage of a connected service. Others are persistent, such as expired credentials, changed field mappings or deleted records. Transient errors may succeed on retry. Persistent ones fail again and can add inconsistency each time.
Next, establish what the failed run already did. If a scenario created a record and failed two modules later, rerunning from the start may create a duplicate. Verify in Make's own documentation whether your configuration offers any way to keep or resume incomplete runs, rather than assuming it does. Where possible, make write steps idempotent, for example by searching for an existing record by a unique key before creating one.
Agree in advance who may trigger recovery and when. A short rule such as 'retry transient errors once, escalate anything else to the owner' stops several people from rerunning the same execution.
Worked example: a decision aid for one failed run
Example (hypothetical, for illustration only): a scenario copies paid invoices from a billing tool into an accounting system every fifteen minutes. One morning a make com error notification reports an authorisation error from the accounting module. A decision aid might run:
Here the useful follow-up is specific. Track the credential's expiry date somewhere visible, and route this scenario's alerts to a shared owner.
- Scope: does run history show one failure or every run since a given time?
- Type: an authorisation error is persistent, so retrying before the credential is fixed only adds failures.
- Side effects: the failure is at the write step, so nothing was created.
- Backlog: list invoice numbers not synced while the scenario was failing.
- Recovery: once an authorised owner restores access, reprocess the backlog once and check for duplicates by invoice number.
- Close: record the cause, the time to detection and one follow-up action.
After the incident: improvement, and where monitoring fits
A short review is enough. Ask what detected the failure, how long it took someone to act, what context the alert lacked, and what single change would prevent a recurrence or shorten detection. Keeping these notes in one log reveals patterns, such as one connection failing repeatedly.
Datvero, which publishes this guide, is designed to watch Make scenarios alongside workflows on other automation platforms. It emphasises alerts a team can act on, diagnosis of what broke and tracking of each incident to closure. Its workflow monitoring page describes a general signal approach covering execution results, heartbeat or silence, volume and business validation, not Make specifics. The page also notes that the service is running while the product is being reworked, so confirm current coverage before relying on it.
The same page states clear limits. Detection works only for signals that have been configured. Monitoring can shorten the time to notice a failure, but it cannot guarantee that third-party services stay available or that a workflow's output is correct for the business. Exact scope depends on platform, plan, permissions and connected configuration. Reliability still rests on how your Make account is set up and how your team operates, and no monitoring setup should sidestep access controls or data-protection obligations.
Frequently asked questions
Why did I not receive a Make error notification when my scenario stopped working?
An error notification usually depends on a run that fails with a recognised error. If the scenario was switched off, its trigger never fired, or an error-handling route absorbed the failure, there may be no failed run to report. Check the scenario's status, run history and error-handler settings, and confirm notification settings in Make's documentation. Also consider an alert for when runs or processed items fall below their normal level.
Is it safe to rerun a failed Make scenario immediately after an error alert?
Not always. A rerun is often reasonable for transient problems such as timeouts or rate limits, provided the failed run wrote nothing elsewhere. Persistent problems such as expired credentials or changed field mappings will simply fail again. If earlier modules created or updated records, rerunning from the start may produce duplicates, so confirm what the failed run already did first.
What information should a useful Make scenario error alert include?
A useful alert lets the recipient decide the next step without investigating from scratch. It should include the scenario name, a link to the failed run, the failing module and its error message, and a record identifier such as an order number. It should also say whether earlier steps wrote data and who the responsible owner is. Avoid copying full personal data, and restrict the alert channel to people who already have access to the underlying systems.
Sources and further reading
These resources provide the wider reference frame. Product statements on this page are limited to the public information provided by Datvero.